ZY Zixin Yin Personal homepage

Overview

Zixin Yin (殷子欣)

I am an incoming AI Research Scientist at Meta in Menlo Park, US, and a Ph.D. student at HKUST, co-advised by Harry Shum and Lionel Ni. My research focuses on agents for visual generation and editing.

I have interned at Meta, IDEA, StepFun, and Xiaobing.ai, working with Lu Yuan, Lei Zhang, Gang Yu, Duomin Wang, and Baoyuan Wang.

I also co-founded Morph Studio and served as its CTO.

Career & impact

Experience

  1. Meta

    AI Research Scientist

    Incoming

  2. Meta

    Research Intern

    May 2026 – Jan 2027

    Video generation, working with Lu Yuan.

  3. Xiaobing.ai

    R&D Lead

    Dec 2025 – May 2026

    Video generation and agents.

    Led the R&D team behind our TikTok's #1 most-viewed short drama of all time [Watch] — and, as of June 2026, 7 titles on the trending chart, including #1 [Watch] and #2.

  4. IDEA & StepFun

    Research Intern

    May 2025 – Nov 2025

    Image and video generation and editing, working with Lei Zhang and Gang Yu.

    Co-authored 9 papers in 6 months — including 3 first-authored, each built from scratch in 30 days, one an oral. Contributions include Step1X-Edit, a state-of-the-art instruction-based image editing model, and UniVerse-1, the first open-sourced audio-video generation model.

  5. Morph Studio

    Co-founder & CTO

    Apr 2023 – Apr 2025

    Video generation.

    Owned the entire technical stack — infrastructure, data, model training, and product — and grew the startup to 1.5M+ users. [TechCrunch]

  6. Xiaobing.ai

    Research Intern

    Feb 2022 – Mar 2023

    Talking head synthesis, working with Duomin Wang and Baoyuan Wang.

Academic background

Education

  1. HKUST

    Ph.D.

    Sep 2021 – Mar 2027

    Computer Science and Engineering, co-advised by Harry Shum and Lionel Ni.

  2. UC Berkeley

    Exchange Student

    Aug 2019 – May 2021

    Computer graphics, working with Carlo H. Séquin on the JIPCAD project.

  3. Sep 2017 – Jul 2021

    Computer Science and Technology (Honors Science Program).

  4. Sep 2015 – Jul 2017

    Honors Youth Program (少年班), entering university at age 15.

Selected research

Publications

Skill Training with Corruption and Reconstruction Loop

Mo Li, Zixin Yin (project lead), Qihao Wu, Ting Cao, Yunxin Liu, Heung-Yeung Shum

arXiv, 2607.27557,

We propose a self-supervised approach that lets agents learn domain-specific skills from existing high-quality human artifacts, without additional human annotations or external rewards. Inspired by diffusion models, it corrupts a human artifact, reconstructs it with the agent's external skill library, and turns the gap into skill updates while keeping model weights frozen. Experiments on short-drama screenwriting show that agents autonomously extract generalizable writing skills from human-authored scripts and substantially improve generation quality.
Motion4Motion: Motion Transfer Across Subjects at Inference

Ling-Hao Chen, Zixin Yin, Duomin Wang, Xianfang Zeng, Gang Yu

ACM SIGGRAPH Conference and Exhibition on Computer Graphics and Interactive Techniques, ACM SIGGRAPH 2026,

Oral Presentation

The first training-free cross-species motion transfer framework that models motion flow instead of skeletons, enabling motion transfer across diverse subjects such as human-to-panda directly at inference time.

ReasonEdit preview

ReasonEdit: Towards Reasoning-Enhanced Image Editing Models

Step1X-Image Team (Core Member)

2026 IEEE Conference on Computer Vision and Pattern Recognition, CVPR 2026,

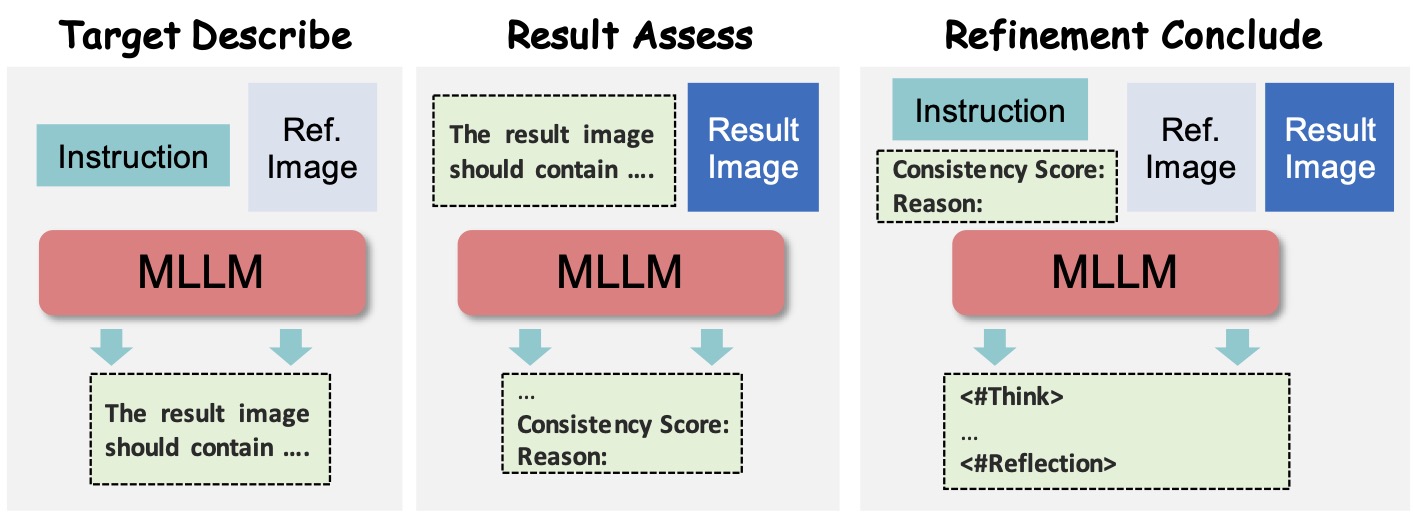
We show that unlocking MLLM reasoning via a thinking–editing–reflection loop significantly improves image editing accuracy by enhancing instruction understanding and automatic error correction, achieving consistent gains over state-of-the-art diffusion-based editors such as Step1X-Edit and Qwen-Image-Edit.

ColorCtrl preview

Training-Free Text-Guided Color Editing with Multi-Modal Diffusion Transformer

Zixin Yin, Xili Dai, Ling-Hao Chen, Deyu Zhou, Jianan Wang, Duomin Wang, Gang Yu, Lionel M. Ni, Lei Zhang, Heung-Yeung Shum

The Fourteenth International Conference on Learning Representations, ICLR 2026,

Completed from scratch in 30 days

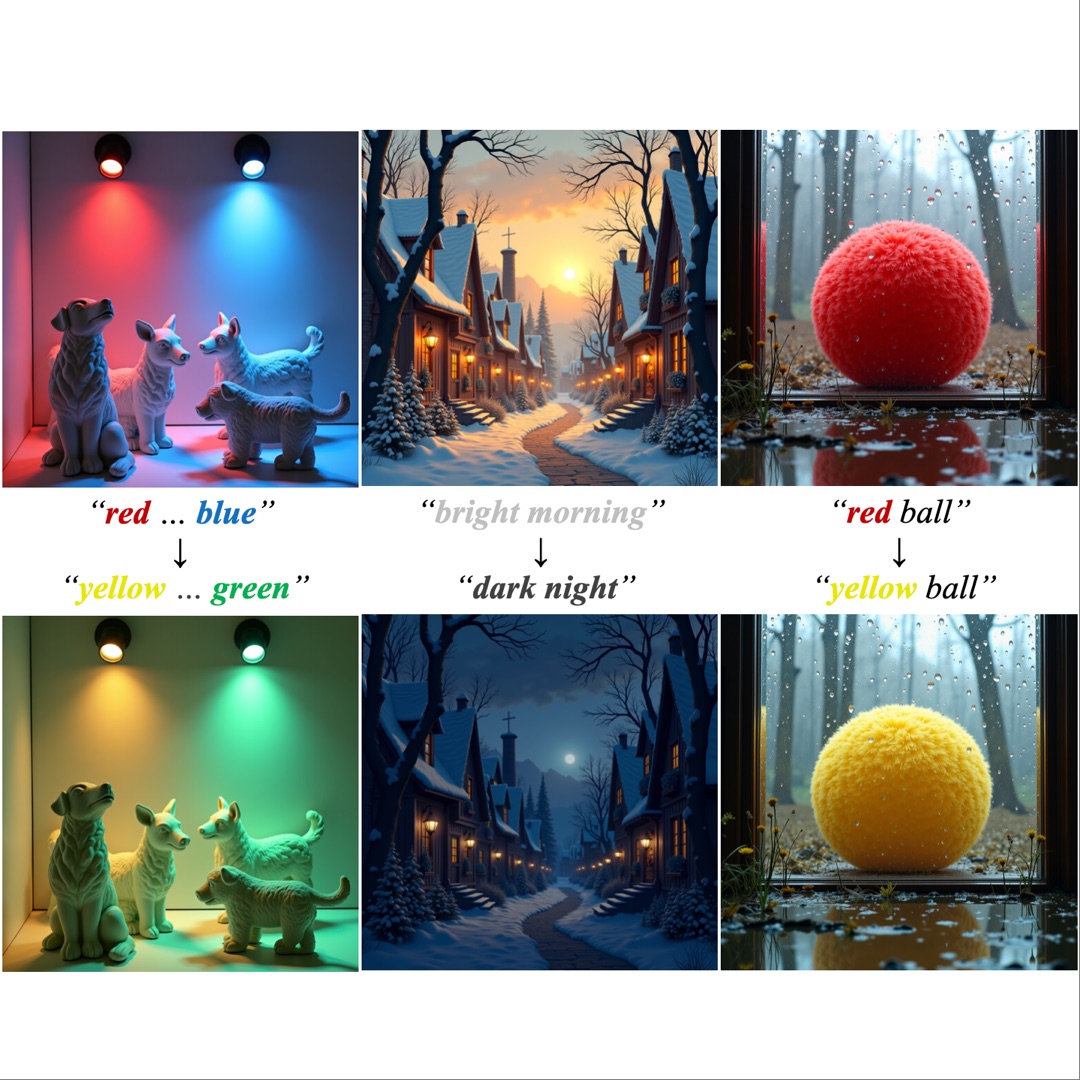
We introduce ColorCtrl, a training-free method for text-guided color editing in images and videos. It enables precise control of color attributes while preserving geometry and material consistency. Experiments on SD3, FLUX.1-dev, and CogVideoX show that ColorCtrl outperforms existing training-free and commercial models, including GPT-4o and FLUX.1 Kontext Max, and generalizes well to instruction-based editing frameworks.

LazyDrag preview

LazyDrag: Enabling Stable Drag-Based Editing on Multi-Modal Diffusion Transformers via Explicit Correspondence

Zixin Yin, Xili Dai, Duomin Wang, Xianfang Zeng, Lionel M. Ni, Gang Yu, Heung-Yeung Shum

The Fourteenth International Conference on Learning Representations, ICLR 2026,

Completed from scratch in 30 days

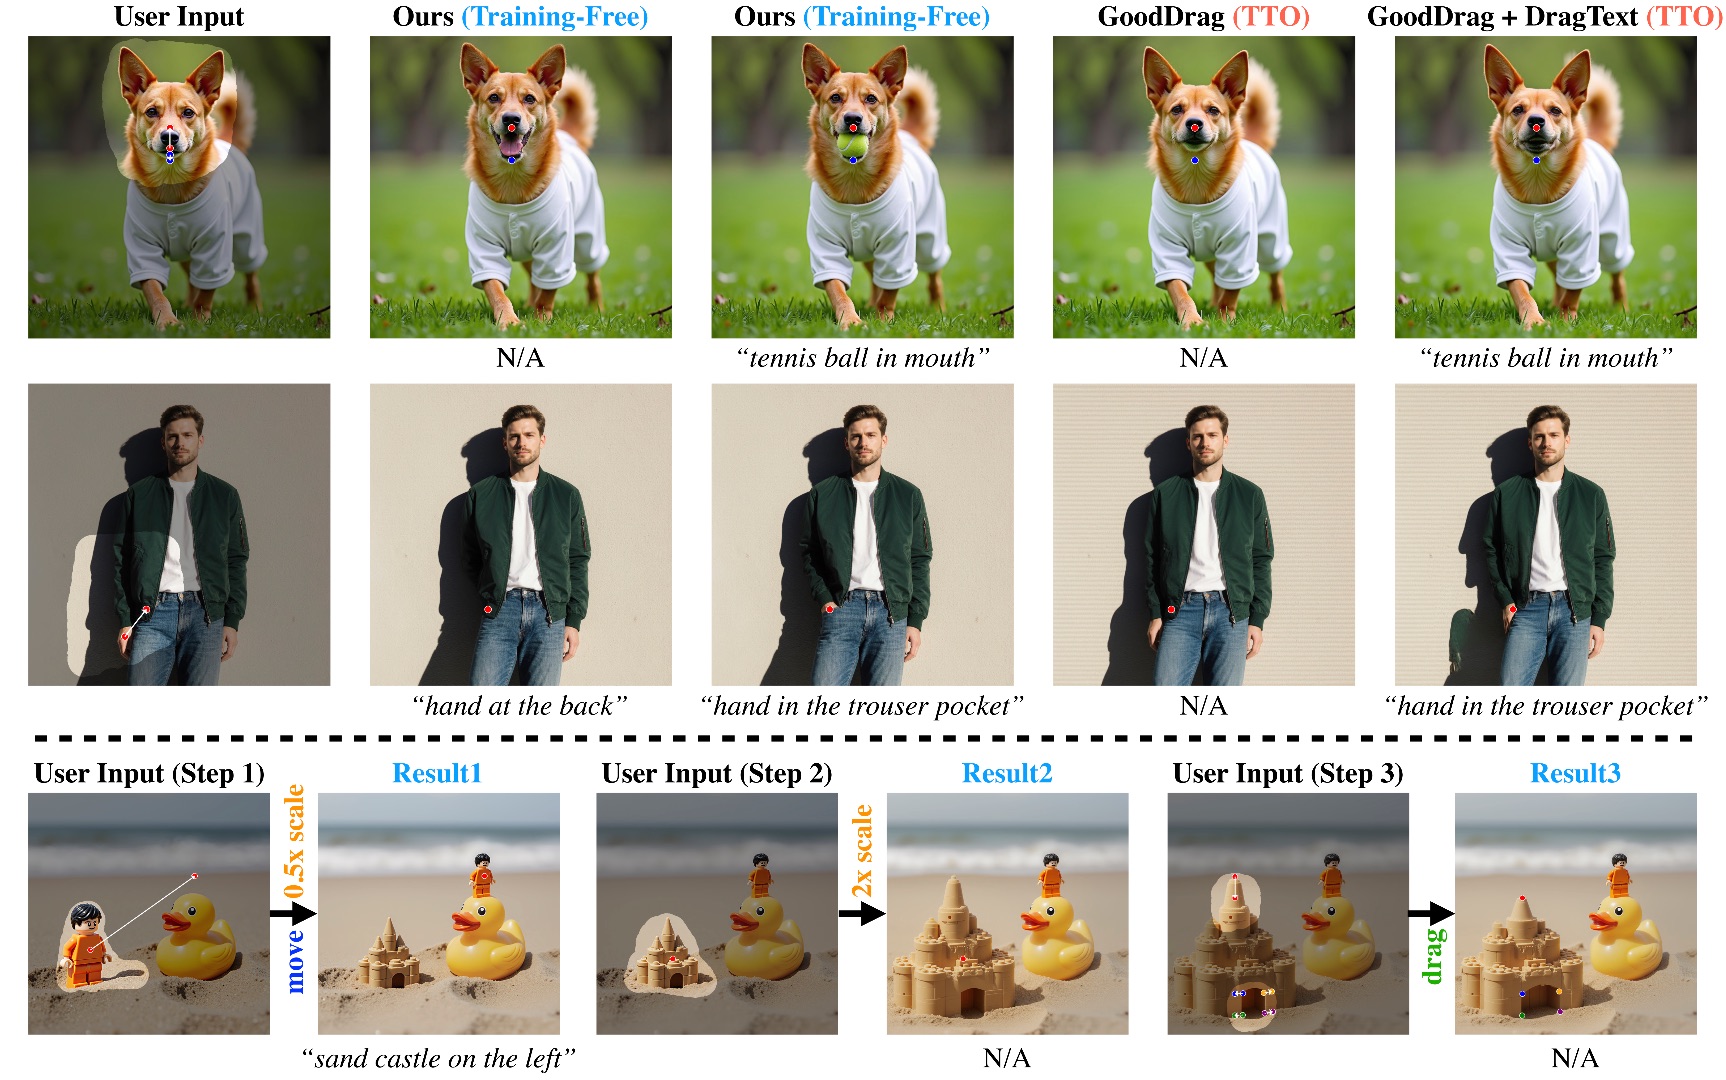
LazyDrag, a drag-based image editing method for Multi-Modal Diffusion Transformers, eliminates implicit point matching, enabling precise geometric control and text guidance without test-time optimization.

SpeakerVid-5M: A Large-Scale High-Quality Dataset for audio-visual Dyadic Interactive Human Generation

Youliang Zhang, Zhaoyang Li, Duomin Wang, Jiahe Zhang, Deyu Zhou, Zixin Yin, Xili Dai, Gang Yu, Xiu Li

The Fourteenth International Conference on Learning Representations, ICLR 2026,

We introduce SpeakerVid-5M, the first large-scale dataset designed specifically for the audio-visual dyadic interactive virtual human task.

ConsistEdit preview

ConsistEdit: Highly Consistent and Precise Training-free Visual Editing

Zixin Yin, Ling-Hao Chen, Lionel M. Ni, Xili Dai

ACM SIGGRAPH Conference and Exhibition on Computer Graphics and Interactive Techniques in Asia, ACM SIGGRAPH Asia 2025,

Oral Presentation (Completed from scratch in 21 days)

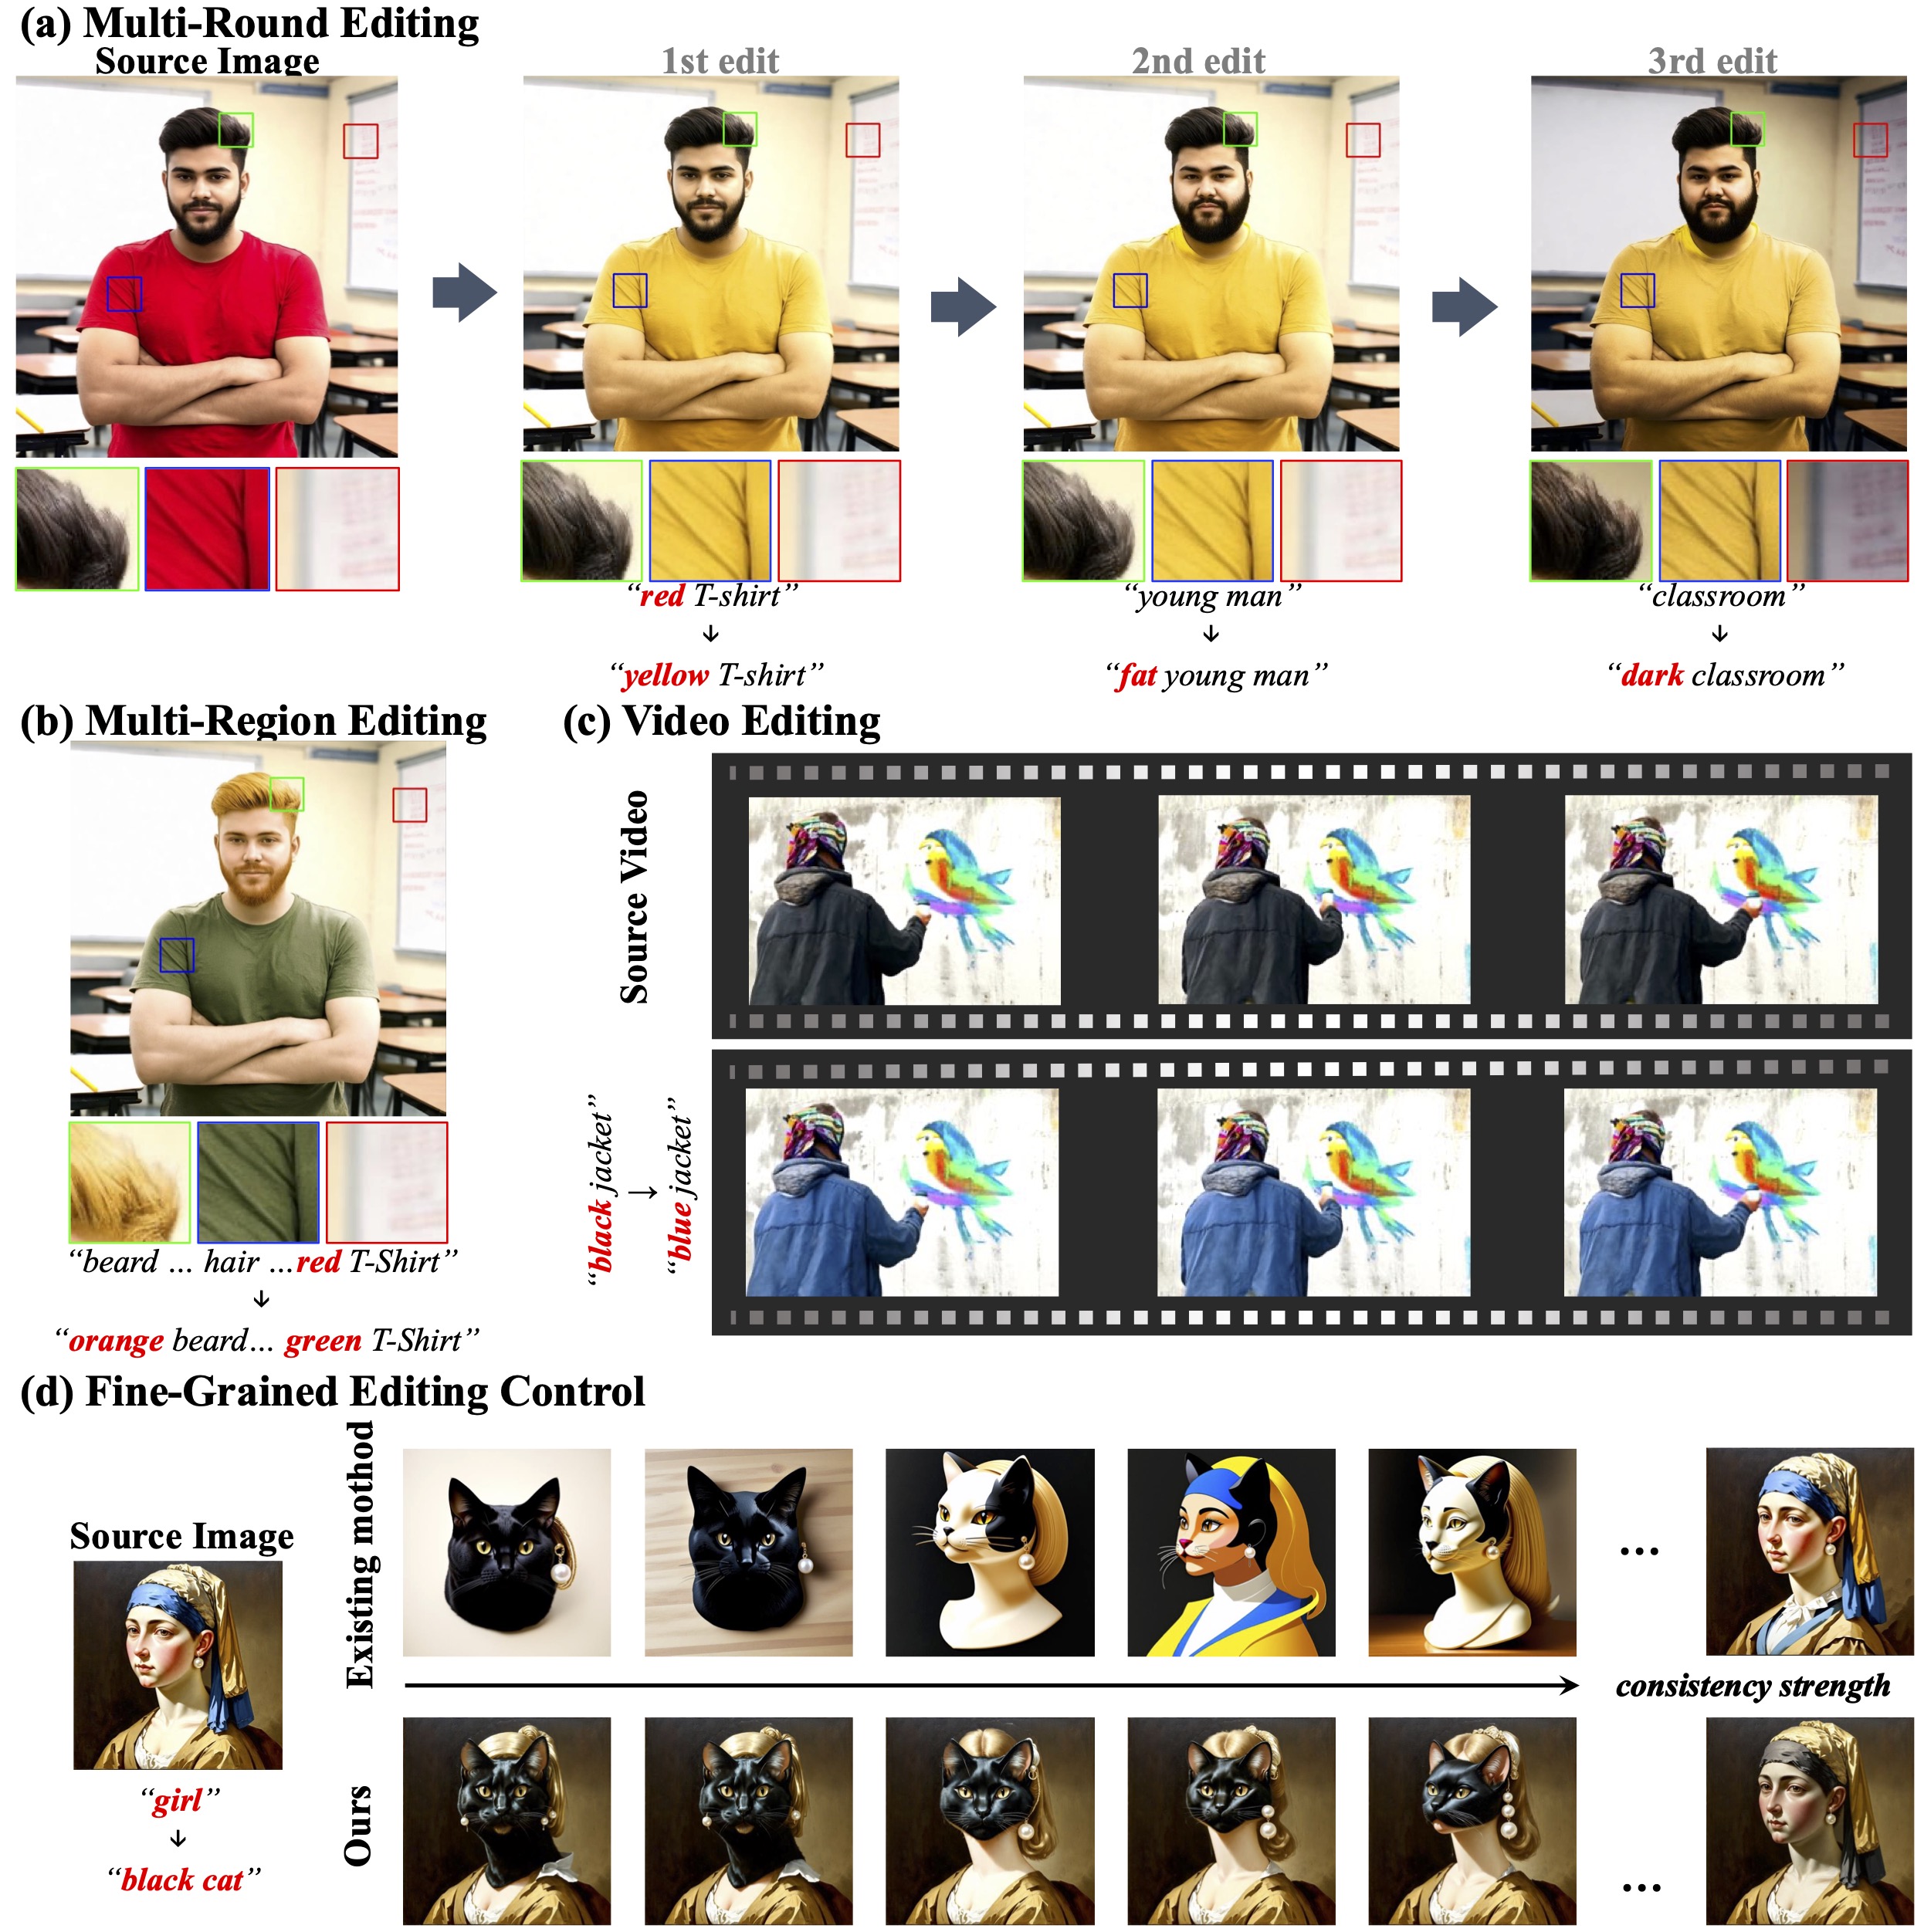
ConsistEdit is a training-free attention control method for MM-DiT that enables precise, structure-aware image and video editing. It supports multi-round edits with strong consistency and achieves state-of-the-art performance without manual design or test-time tuning.

Motion2Motion: Cross-topology Motion Retargeting with Sparse Correspondence

Ling-Hao Chen, Yuhong Zhang, Zixin Yin, Zhiyang Dou, Xin Chen, Jingbo Wang, Taku Komura, Lei Zhang

ACM SIGGRAPH Conference and Exhibition on Computer Graphics and Interactive Techniques in Asia, ACM SIGGRAPH Asia 2025,

Oral Presentation

This work addresses animation retargeting across characters with differing skeletal topologies. Motion2Motion is a novel, training-free framework that requires only a few target motions and sparse bone correspondences. It overcomes topological inconsistencies without large datasets. Extensive evaluations show strong performance in both similar and cross-species settings, with applications in user-facing tools.

UniVerse-1: Unified Audio-Video Generation via Stitching of Experts

Duomin Wang, Wei Zuo, Aojie Li, Ling-Hao Chen, Xinyao Liao, Deyu Zhou, Zixin Yin, Xili Dai, Daxin Jiang, Gang Yu

arXiv, 2509.06155,

We introduce UniVerse-1, a unified, Veo-3-like model capable of simultaneously generating coordinated audio and video. To enhance training efficiency, we bypass training from scratch and instead employ a stitching of expertise technique.

Talking Head Generation with Probabilistic Audio-to-Visual Diffusion Priors

Zhentao Yu, Zixin Yin (co-first), Deyu Zhou, Duomin Wang, Finn Wong, Baoyuan Wang

2023 IEEE International Conference on Computer Vision, ICCV 2023,

We introduce a simple and novel framework for one-shot audio-driven talking head generation. Unlike prior works that require additional driving sources for controlled synthesis in a deterministic manner, we instead probabilistically sample all the holistic lip-irrelevant facial motions to semantically match the input audio while still maintaining both the photo-realism of audio-lip synchronization and the overall naturalness.

Progressive Disentangled Representation Learning for Fine-Grained Controllable Talking Head Synthesis

Duomin Wang, Yu Deng, Zixin Yin, Heung-Yeung Shum, Baoyuan Wang

2023 IEEE Conference on Computer Vision and Pattern Recognition, CVPR 2023,

We present a novel one-shot talking head synthesis method that achieves disentangled and fine-grained control over lip motion, eye gaze&blink, head pose, and expression. We represent different motions via disentangled latent representations and leverage an image generator to synthesize talking heads from them.